
Best Serverless GPU Providers
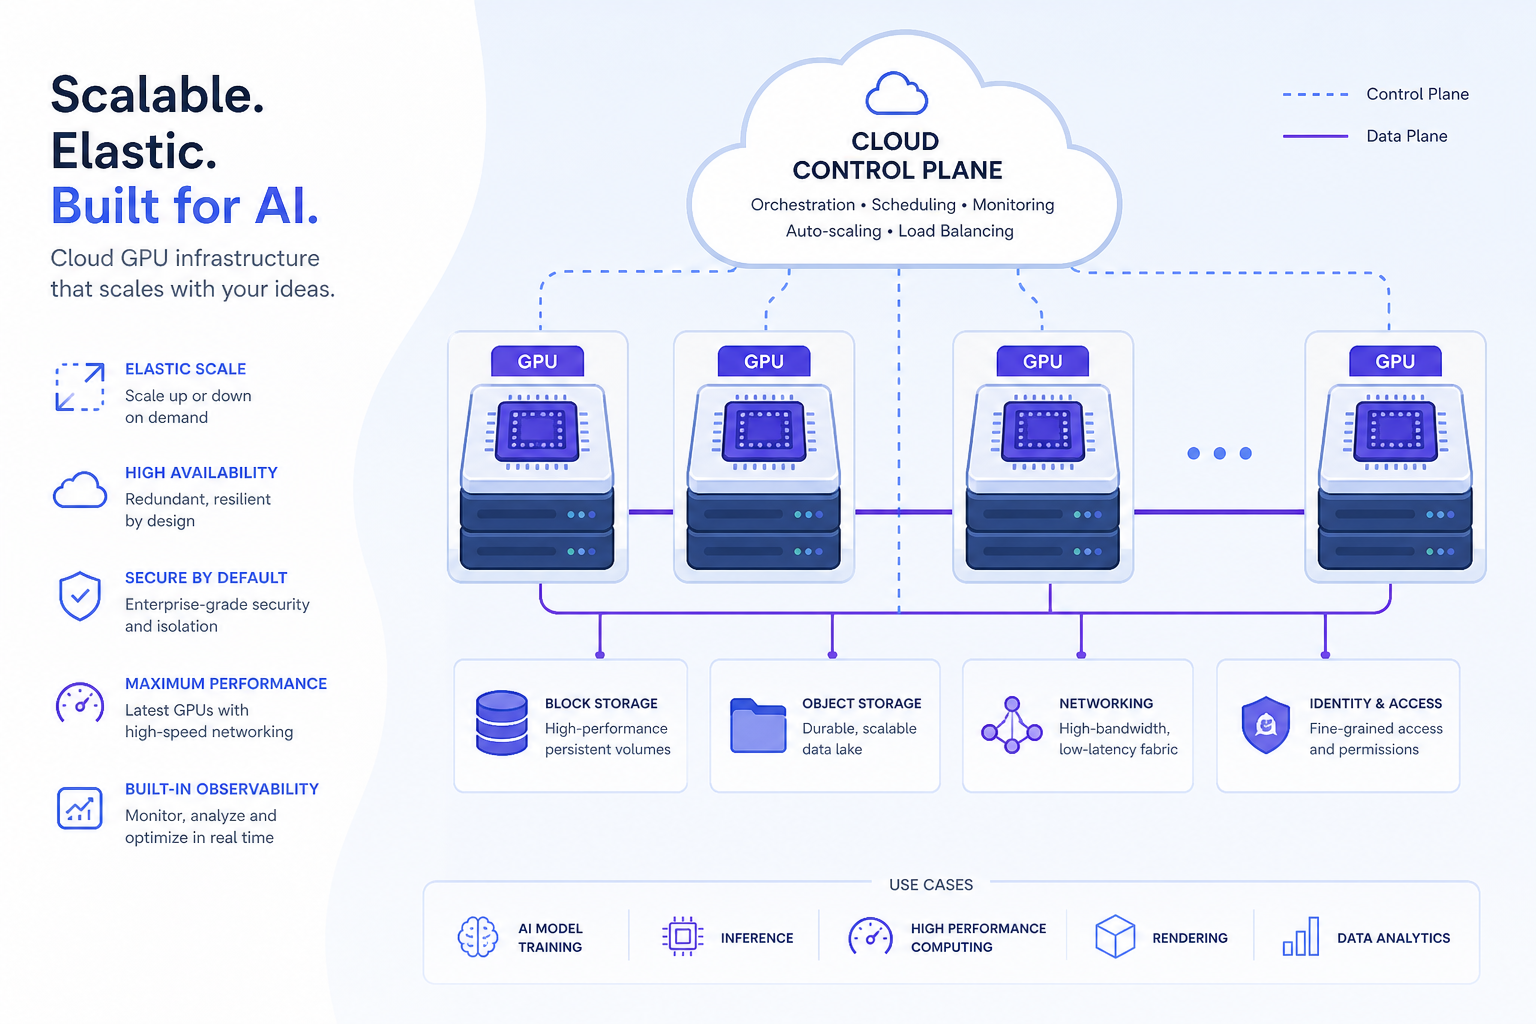
If you need GPU compute that scales to zero, bills by the second, and avoids idle-node costs, the best serverless GPU providers in 2026 are RunPod Serverless, Modal, Together AI, Salad Cloud, Nebius, and CoreWeave.
Which providers consistently rank as top serverless GPU solutions?
Several comparisons and rankings spotlight six leading providers:
- RunPod Serverless – frequently cited as “best overall” due to flexible container-based deployments and competitive pricing ([gpuhosted.com](https://gpuhosted.com/en/serverless-gpu/)).
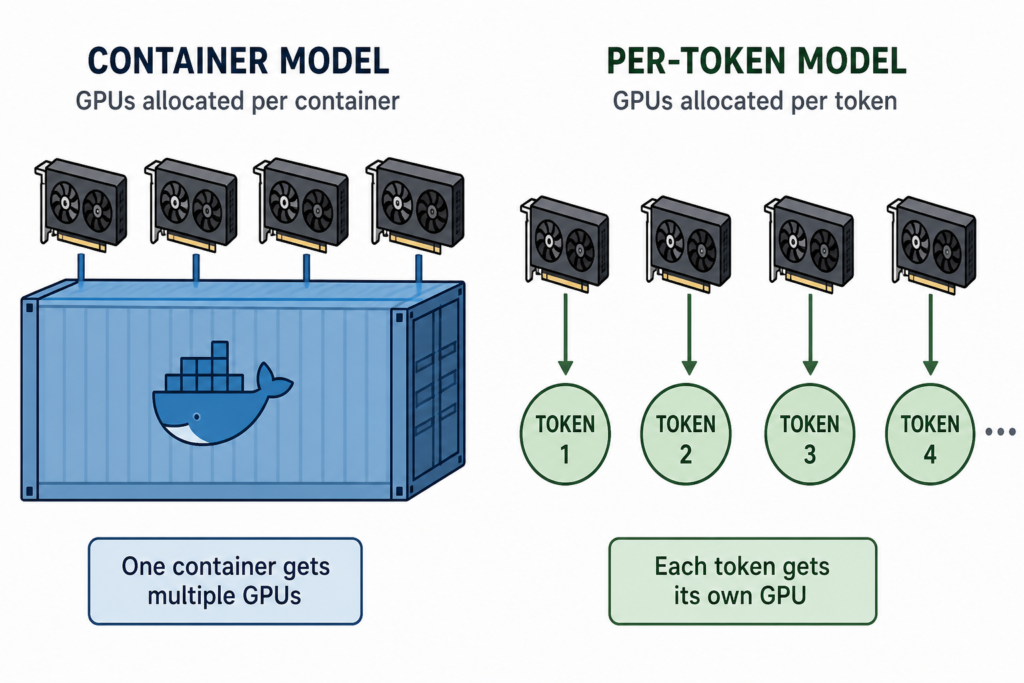
- Together AI – optimal for per‑token LLM APIs; zero cold start, but limited to hosted models ([gpuhosted.com](https://gpuhosted.com/en/serverless-gpu/)).
- Salad Cloud – leverages distributed residential GPUs like RTX 4090s; cost‑effective but network reliability varies ([gpuhosted.com](https://gpuhosted.com/en/serverless-gpu/)).
- Modal – tailored for developers, especially Python-first; offers per-second billing ([aicostcalculators.com](https://aicostcalculators.com/gpu-cloud-pricing-comparison/)).
- Nebius – Kubernetes-native, integrates into existing K8s environments smoothly ([gpuhosted.com](https://gpuhosted.com/en/serverless-gpu/)).
- CoreWeave – enterprise-grade scale, reserved capacity discounts (~60%) ([aicostcalculators.com](https://aicostcalculators.com/gpu-cloud-pricing-comparison/)).
How does pricing compare across providers?
Pricing depends heavily on GPU model, billing granularity, and deployment style. Here’s a comparison table based on June–August 2026 verified data:
| Provider | GPU / Tier | Billing | Approx. Rate (USD/hr) | Strength |
|---|---|---|---|---|
| RunPod Serverless | L40S flex | per-second | $1.69–$1.90 | Flexible containers, multi-region |
| Modal | L40S, A100‑80GB | per-second | $1.95 (L40S), $2.78 (A100) | Developer-friendly, Python build |
| Lambda / L | A100 40GB | on-demand | $1.99 | Hyperscaler scale |
| Inferless | A10 shared | per-second | $0.00017/sec (~$0.61) | Fine-grained billing, economical |
| CoreWeave | H100 (capacity block) | reserved | $3.93 (capacity) | Enterprise volume discounts |
Data sources:
- DeployCue verified June 2026 pricing ([deploycue.com](https://deploycue.com/serverless-gpu/));
- CloudGPUPrices serverless catalog updated September 1, 2026 ([cloudgpuprices.com](https://cloudgpuprices.com/serverless));
- GPUCloud Pricing Tracker August 31, 2026 ([app.siliconanalysts.com](https://app.siliconanalysts.com/tools/cloud-pricing));
- AI Cost Calculators April 2026 breakdown ([aicostcalculators.com](https://aicostcalculators.com/gpu-cloud-pricing-comparison/)).
What factors affect your choice?
- Billing granularity: Per‑second billing (Modal, Inferless, RunPod) shrinks costs for bursty inference jobs.
- Cold starts: Container-based providers have cold start latencies (2–15s); per-token APIs (Together AI) avoid cold starts but limit custom models ([gpuhosted.com](https://gpuhosted.com/en/serverless-gpu/?utm_source=openai)).
- GPU models needed: Hyperscalers (Lambda, CoreWeave) offer a broader GPU fleet; neoclouds offer specific SKUs with cost efficiency.
- Scale & SLA: CoreWeave for enterprise scale and reserved discount; Salad for low-cost inference with variable reliability; Nebius for K8s-native workflows.
- Deployment model: Container/serverless functions (RunPod, Modal, Nebius), per-token APIs (Together AI), or distributed models (Salad).
How to choose the right provider
- Short‑list based on your workflow: e.g., container deployment → RunPod or Modal; token API only → Together AI; enterprise scale → CoreWeave.
- Compare billing models and estimate your monthly usage. Per‑second options save for low‑utilization workloads; reserved blocks save on continuous high usage.
- Test with a representative workload. Measure cold start latency, throughput, and total cost for a real inference run.
- Check region availability and latency. Because distributed providers like Salad can suffer inconsistent reachability, run latency tests.
- Factor in support and SLAs if using for production. Enterprise providers like CoreWeave offer formal support; self-service options require in-house ops capacity.
When does serverless GPU make sense?
Serverless GPUs deliver best ROI when:
- Your workload is intermittent or unpredictable—avoids paying for idle nodes.
- Inference tasks are short-lived or bursty—per-second billing eliminates rounding waste.
- You require fast deployment, not full cluster management—serverless abstracts infra.
- You’re experimenting or need flexible scaling without long-term commitments.
Reserved or dedicated node rentals still beat serverless on cost when utilization is predictable and sustained. But most cost-conscious teams benefit from mixing serverless for experimentation and spot workloads, with reserved blocks for baseline demand.
Frequently Asked Questions
About the Author: Nhon Dang is a cloud infrastructure and operations professional with over 10 years of hands-on experience in cloud services, infrastructure, and business operations. His expertise includes virtual machines, Kubernetes, object storage, managed databases, Apache Kafka, and cloud GPU infrastructure. Nhon focuses on practical, experience-driven guidance to help engineers and business leaders optimize cloud computing decisions.