Intel Arc B580 for Local AI: 12GB at $249
Discover how the Intel Arc B580 (12GB GDDR6, $249) fits into local AI workflows, its specs, performance vs competitors, tips for deployment, and when it’s a smart pick.
Discover how the Intel Arc B580 (12GB GDDR6, $249) fits into local AI workflows, its specs, performance vs competitors, tips for deployment, and when it’s a smart pick.
In this detailed guide, we break down the RTX 5090 specs, MSRP vs actual prices, performance impact, system requirements, and whether it’s worth the investment.
A direct, in‑depth comparison of spot versus on‑demand GPU instances—when to use each, real‑world cost gaps, and how to adopt spot effectively without losing work.
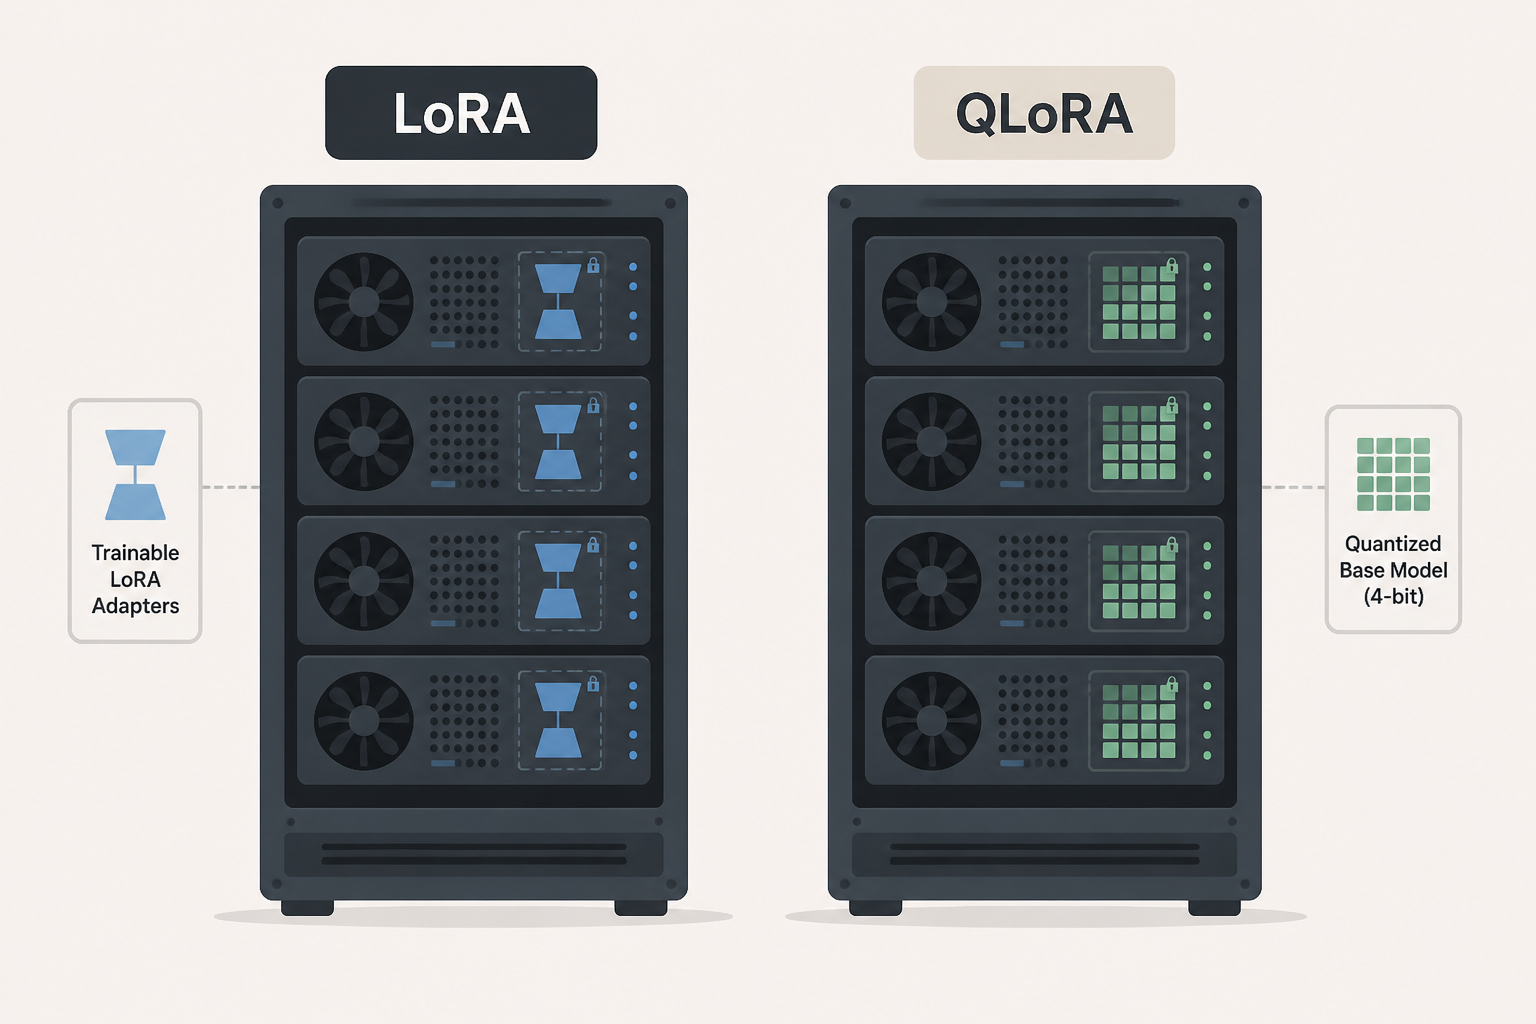
LoRA and QLoRA are adapter‑based fine‑tuning techniques. This article compares how they differ, when to choose each, and how to optimize for cost, memory, and quality.
Which GPU should you choose to train or fine‑tune LLMs in 2026? This guide compares performance, VRAM, bandwidth, cost, and use cases—from cloud‑scale A100 to frontier B200 and local RTX options.
The RTX 5060 (8 GB GDDR7) is budget‑friendly for gaming and light local AI, but 8 GB VRAM is an absolute ceiling. Learn which LLMs fit, real performance data, offload strategies, and upgrade‑when advice.
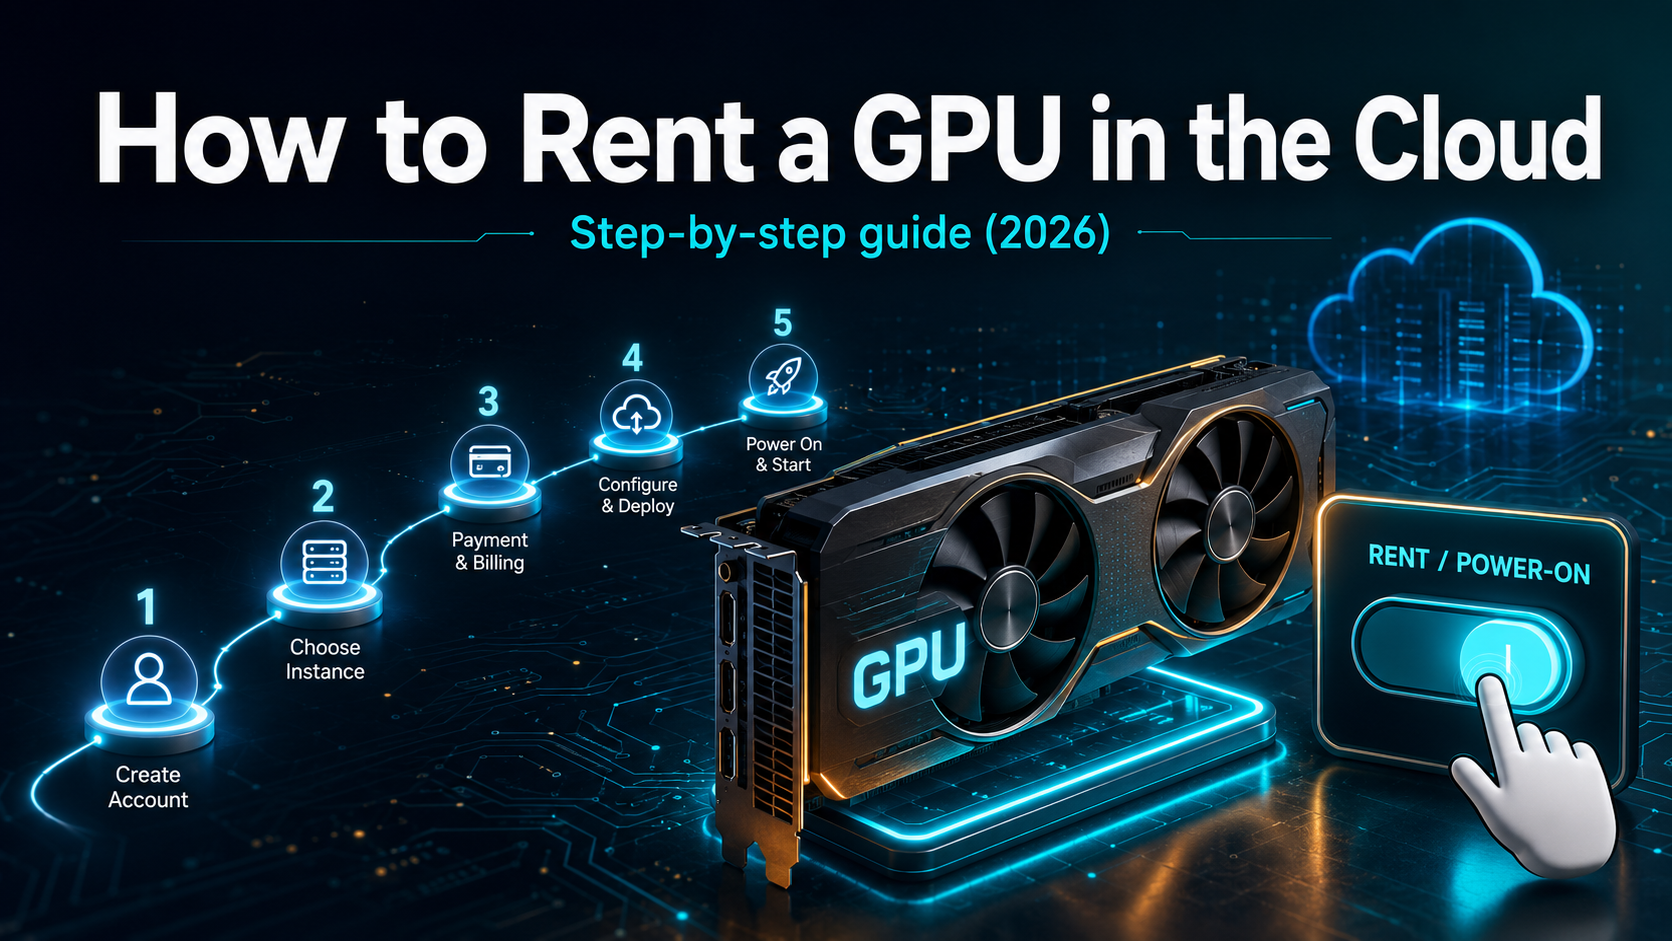
To rent a cloud GPU: (1) pick a provider like RunPod or Vast.ai, (2) choose a GPU that fits your model's VRAM needs, (3) launch an instance on-demand or spot,…
A cloud GPU is a graphics processing unit you rent remotely over the internet instead of buying physical hardware. You pay by the hour — or even by the second…
A 70-billion-parameter LLM needs about 140GB of VRAM for FP16 inference (2 bytes per parameter), or roughly 35–40GB when quantized to 4-bit. Training needs 1.5–4x more than inference for optimizer…