
Last updated: September 13, 2026
In brief: The NVIDIA B200 is a Blackwell‑architecture data‑center GPU offering ~192 GB HBM3e memory, ~8 TB/s bandwidth, and powerful tensor performance across FP4–FP64. It underpins platforms like HGX B200 and DGX B200 for large‑scale AI workloads.
What is NVIDIA B200?
NVIDIA B200 is a high‑end data‑center GPU built on the Blackwell architecture, designed for large‑scale AI training, inference, and HPC workloads.
What architectural features define the B200?
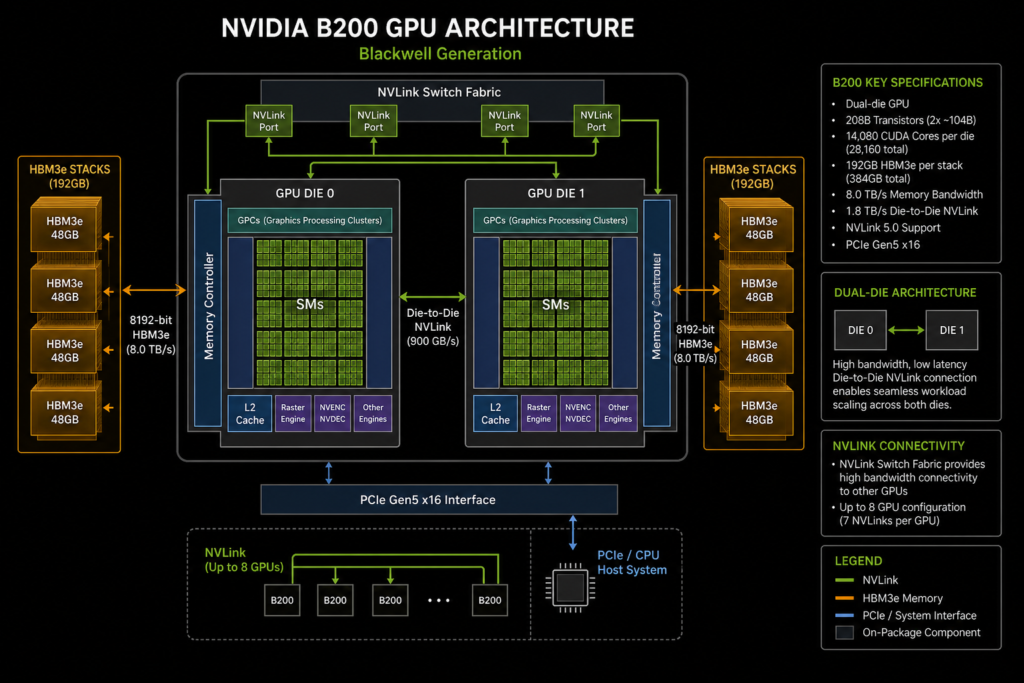
- Dual reticle‑limited GPU dies fused behind one lid, linked by a 10 TB/s interconnect for logical single GPU operation ([elprocus.com](https://www.elprocus.com/nvidia-blackwell-b200-architecture)).
- 192 GB HBM3e memory and ~8 TB/s memory bandwidth ([era.dev](https://era.dev/learn/b200)).
- 5th‑generation Tensor Cores, 2nd‑generation Transformer Engine supporting FP4 and FP8; FP4 dense performance up to ~9 PFLOPS ([spheron.network](https://www.spheron.network/blog/nvidia-b200-complete-guide)).
- NVLink bandwidth ~1.8 TB/s per GPU ([spheron.network](https://www.spheron.network/blog/nvidia-b200-complete-guide)).
How does B200 compare to prior NVIDIA GPUs?
- Memory is double or more compared to Hopper‑generation (e.g., H100/H200), and throughput is substantially improved ([developer.nvidia.com](https://developer.nvidia.com/blog/?p=106112)).
- FP16 inference throughput is ~2.3× faster than HGX H100 and up to 15× more energy‑efficient in inference scenarios ([developer.nvidia.com](https://developer.nvidia.com/blog/?p=106112)).
What platform variants include B200?
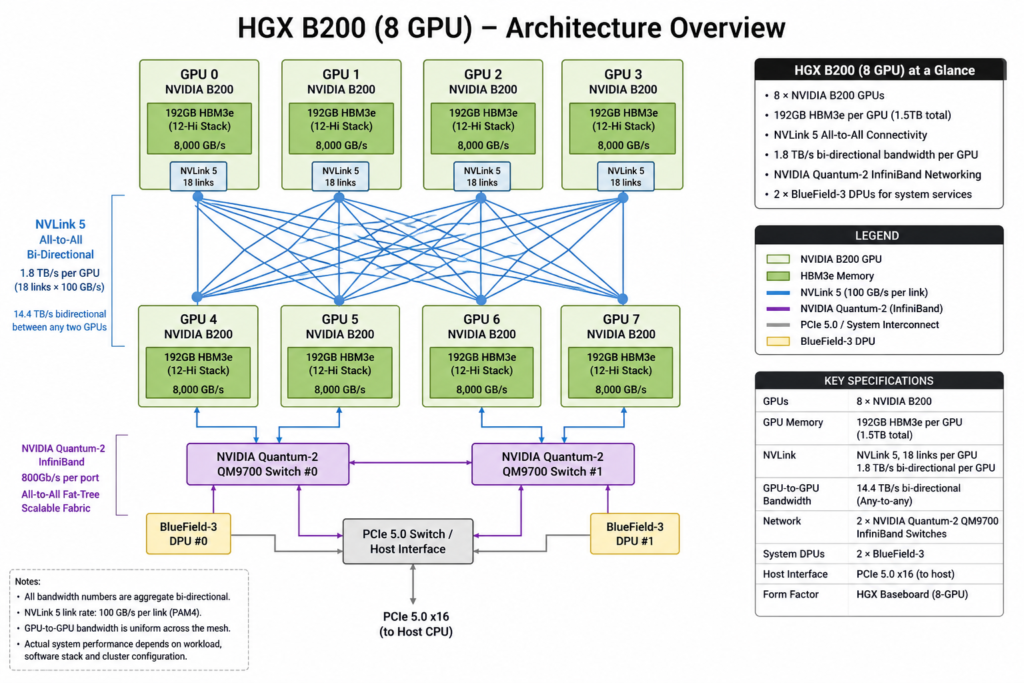
HGX B200 baseboard
An 8‑GPU board delivering ~144 PFLOPS (FP4 Tensor Core), 1.44 TB pooled GPU memory, 64 TB/s aggregate bandwidth, and 14.4 TB/s NVLink‑NVSwitch interconnect ([docs.nvidia.com](https://docs.nvidia.com/enterprise-reference-architectures/hgx-ai-factory-h100-h200-b200/latest/components.html)).
DGX B200 system
Fully integrated rack appliance combining 8 B200 GPUs with high‑speed NVSwitch/NVLink, dual Intel Xeon Platinum CPUs (112 cores total), 2 TB system memory (expandable to 4 TB), high‑speed storage, networking, and AI‑optimized software stack ([nvidia.com](https://www.nvidia.com/en-au/data-center/dgx-b200/)).
Difference between B200, GB200, HGX, and DGX
- B200 is the standalone GPU chip.
- GB200 combines one Grace CPU with two B200 GPUs (Grace‑Blackwell superchip) ([modal.com](https://modal.com/blog/nvidia-blackwell)).
- HGX and DGX are system platforms leveraging multiple B200 GPUs for enterprise or rack‑scale performance ([modal.com](https://modal.com/blog/nvidia-blackwell)).
Specifications comparison table
| Metric | B200 GPU | HGX B200 (8‑GPU) | DGX B200 System |
|---|---|---|---|
| Memory (total) | 192 GB | 1.44 TB | 1.44 TB |
| Memory bandwidth | ~8 TB/s | 64 TB/s | 64 TB/s |
| FP4 Tensor Perf | ~9 PFLOPS | ~144 PFLOPS | ~144 PFLOPS |
| NVLink / NVSwitch | 1.8 TB/s per GPU | 14.4 TB/s aggregate | 14.4 TB/s aggregate |
| System CPUs | — | x86 recommended | 2 × Intel Xeon Platinum 8570 |
When to choose B200?
Recommended when you need high GPU memory capacity (192 GB), massive multi‑GPU scaling, or higher precision and throughput in model training/inference compared to Hopper‑based deployments. B200-based systems significantly improve performance per watt and reduce TCO in AI factory scenarios ([developer.nvidia.com](https://developer.nvidia.com/blog/?p=106112)).
Platforms like HGX platforms overview or DGX B200 deep dive provide entry points for adopting B200 in enterprise AI infrastructure.
How to deploy B200 for maximum efficiency?
- Select appropriate cooling option (air‑ or liquid‑cooled HGX B200 or DGX B200) based on rack power and thermal budget.
- Pair with CPUs and system memory per NVIDIA guidelines — dual‑socket x86 with ≥1.5 TB memory is typical ([docs.nvidia.com](https://docs.nvidia.com/enterprise-reference-architectures/hgx-ai-factory-h100-h200-b200/latest/components.html)).
- Optimize power and software stack — enable transformer sparsity, mixed‑precision (FP4/FP8), and NVIDIA AI Enterprise with Run:ai or other orchestration layers.
- Consider confidential computing support via HGX B200 confidential mode if needing NVLink encryption and secure multi‑GPU setups ([confidentialnodes.com](https://confidentialnodes.com/gpus/nvidia-blackwell-b200)).
Example calculation: training transformer model
Suppose a 500B‑parameter transformer needing ~1.2 TB total GPU memory across 8 GPUs. B200 provides that natively (8 × 192 GB = 1.536 TB) with NVLink‑NVSwitch interconnect. FP4 training throughput (~144 PFLOPS) can reduce training time vs H100 systems by 2–3×, saving days of runtime. Verify exact time savings with open‑source benchmarks on your model — see AI training benchmarks.